HyFlowSE: Hybrid End-to-End Flow-Matching Speech Enhancement via Generative–Discriminative Learning Online Supplement
Authors
Yang Zhang, Wenbin Jiang, Zhen Wang, KaiYing Wu, Wen Zhang, and Fei Wen
Abstract
Generative speech enhancement (SE) methods, typically implemented with diffusion or flow matching, exhibit strong generalization to unseen acoustic conditions. However, they often underperform discriminative approaches in matched, in-domain settings. Recent attempts to close this gap have relied on pretrained discriminative models or cascaded multi-flow architectures, which add inference steps and increase computational cost. To address these limitations, we propose HyFlowSE, a flow matching SE framework with hybrid generative–discriminative learning. HyFlowSE leverages neural ordinary differential equations (ODEs) for end-to-end training and jointly optimizes generative and discriminative objectives within a single model. Experiments on popular benchmark datasets show that HyFlowSE, with only 5.2 M parameters, outperforms other generative SE methods across nearly all evaluation metrics, with especially pronounced gains at low signal-to-noise ratios.
The VoiceBank+DEMAND dataset is used for demo.
Audio samples of the test set we processed are available at the repository (voicebank).
FlowSE: Flow matching based speech enhancement
CasFlowSE: Speech enhancement based on cascaded two flows
Datasets
Compared methods
Audio Samples
| Model\id(noise) | p257_008(cafe) | p257_033(living) | p257_106(bus) | p232_250(office) | p232_409(psquare) |
|---|---|---|---|---|---|
| Clean | |||||
| Noisy | |||||
| FlowSE | |||||
| CasFlowSE | |||||
| HyFlowSE | |||||
| HyFlowSE(M)$ | |||||
| HyFlowSE(S)$ | |||||
| HyFlowSE(T)$ |
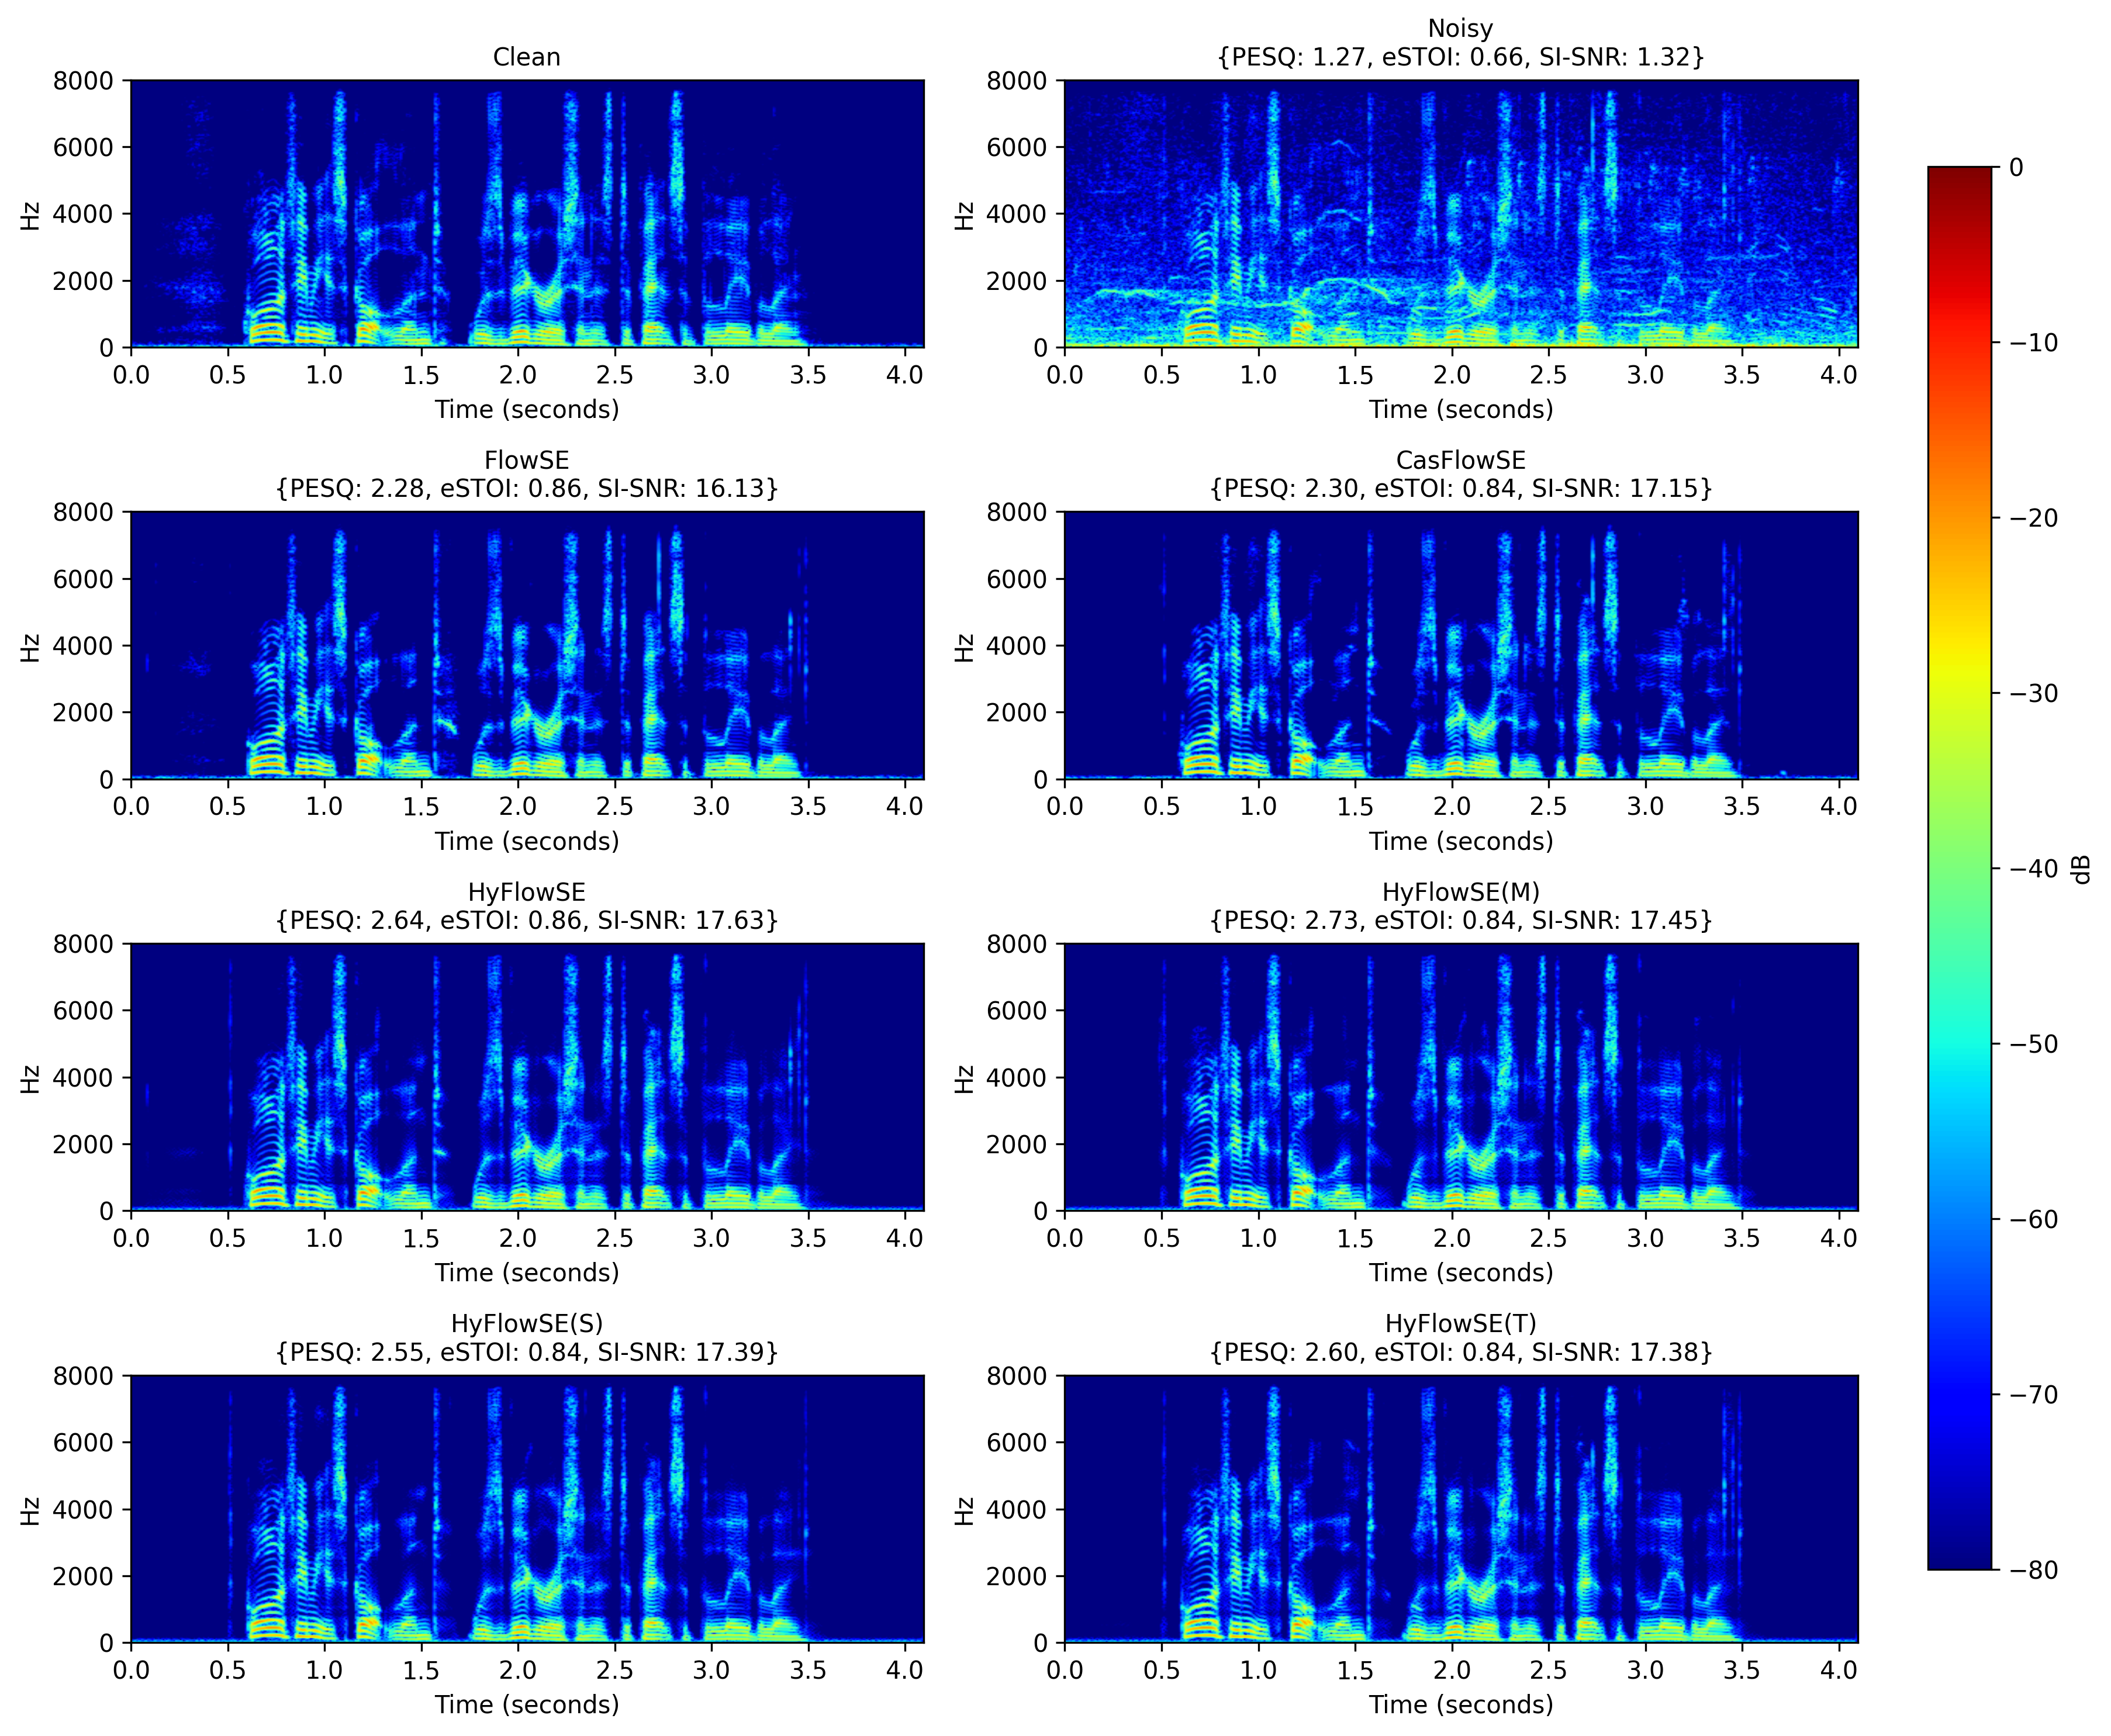
Spectrogram of the samples in last column